Editorial date: 3 November 2026
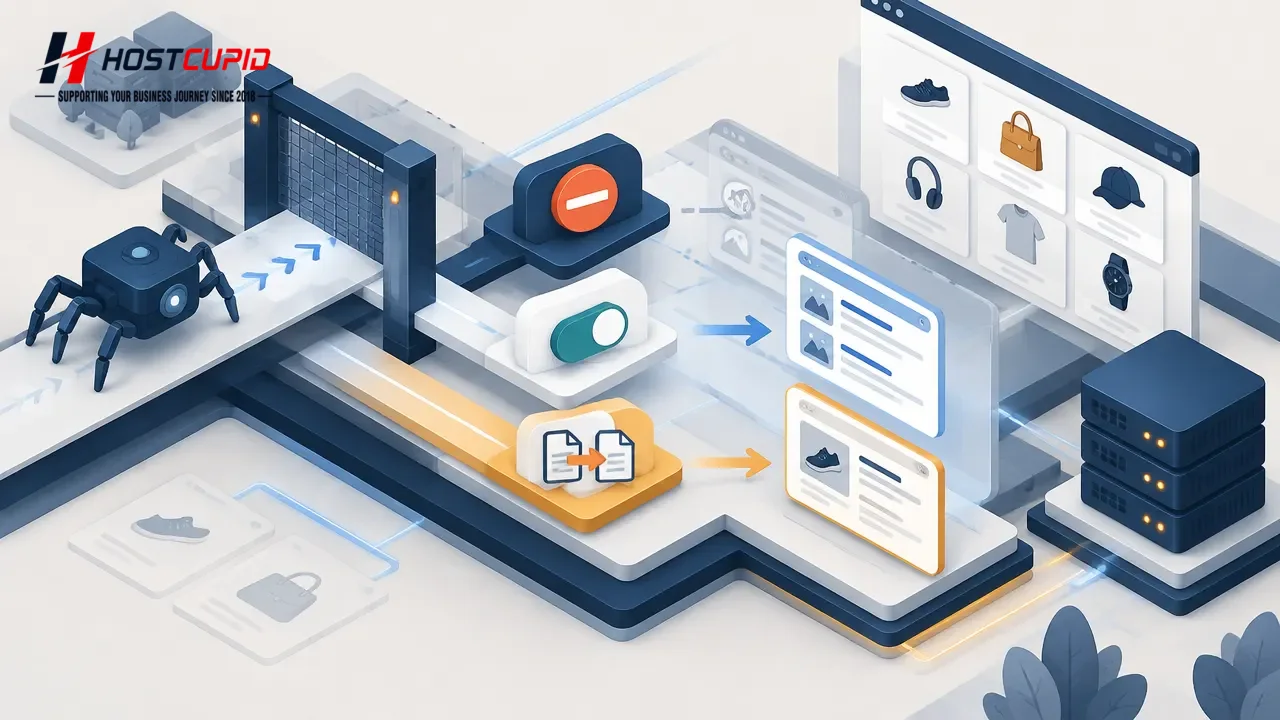
Short answer: use robots.txt to manage crawler access, noindex to ask search engines not to show an accessible page in results, and a canonical tag to indicate the preferred URL among duplicate or similar pages. They solve different problems, so combining them without a plan can work against your goal.
This distinction matters to WordPress owners, online stores and developers who are cleaning up staging pages, filter URLs or duplicate versions. A robots rule is not a privacy lock, and neither robots.txt nor noindex replaces password protection for private material.
What is the difference between robots.txt and noindex?
A robots.txt file gives crawler instructions about which URLs they may request. It is commonly useful when you want to limit crawling of low-value URL patterns, such as endless combinations of product filters. Google notes that a disallowed page’s URL may still appear in results if it is discovered elsewhere, even though its contents cannot be crawled.
A noindex directive is different: it asks a search engine that supports it not to include the page in its results. The crawler must be allowed to fetch the page to read that directive. If robots.txt blocks that same URL, Google cannot see the page-level noindex instruction, so do not stack a disallow rule on a page you need Google to crawl in order to process noindex.
A canonical tag is a signal about which URL should represent duplicate or very similar content. It is a hint, not a command, and is not a substitute for robots.txt when your aim is to reduce crawler requests. For ecommerce sites, Google recommends consistent URL signals, including internal links, sitemap entries and canonical tags.
Choose the control by the outcome you need
- Keep a page out of search results: allow crawling and use a page-level noindex directive, or restrict the page behind authentication. For confidential data, use access controls; robots.txt is public and does not secure content.
- Reduce crawling of unwanted URL patterns: consider a carefully targeted robots.txt disallow rule, after checking that important content and resources are not caught by it.
- Identify the preferred version of duplicate content: use consistent canonical signals and link to the preferred URL internally.
- Prevent visitors and crawlers from accessing a private staging site: use password protection or equivalent access control, not merely a search-engine instruction.
For an online shop, a useful default is to keep product pages and important category listings crawlable, while assessing whether parameter combinations from sorting and filtering deserve crawling or search visibility. Google warns that faceted navigation can create very large URL spaces and consume server resources. Do not automatically block every filtered URL: some may be useful landing pages if they have distinct, valuable content and a real search purpose.
A safe review for WordPress and ecommerce sites
- Write down the intended outcome. Is the goal to stop search visibility, reduce crawler traffic, consolidate duplicates or protect private content? Choose the mechanism only after answering this.
- Check WordPress visibility. In the dashboard, review Settings → Reading → Search Engine Visibility. WordPress documents that enabling “Discourage search engines from indexing this site” outputs a noindex instruction when the theme supports it. Before launch, check that the setting matches the live site's intended visibility.
- Inspect the actual response. Open the affected page as a visitor and inspect its HTML or HTTP headers for robots directives. Check that a page meant to be indexed is not accidentally marked noindex, and that any noindex page remains crawlable so the instruction can be read.
- Review robots.txt from the domain root. Visit
https://yourdomain.example/robots.txtand confirm the rules are plain text and target only the intended paths. Robots rules apply to the specific protocol, host and port, so inspect the correct live hostname as well as staging where relevant. - Check URL patterns before blocking. Test representative product, category, pagination and filter URLs. A broad rule can unintentionally cover a valuable page or required resource. For filter combinations with no results, Google recommends returning a real 404 rather than redirecting every empty result to one generic page.
- Verify in Search Console. Use URL Inspection to check the indexed version and, where available, test the live URL. Review the Page Indexing report for patterns after changes. A crawl or indexing request does not guarantee immediate inclusion or removal, so monitor rather than repeatedly submitting the same URL.
Before changing rules: save a copy of the existing robots.txt file and record the exact URLs you expect the change to affect. A small, reversible test is safer than a broad site-wide block.
What should a site owner do next?
For a WordPress site being prepared for launch, confirm that search visibility is enabled when the site should be public, then inspect the homepage and a key page for unintended noindex directives. If your goal is to hide a development copy, require a password rather than relying on robots.txt. For a shop with many filter combinations, first identify which filtered pages genuinely deserve search visibility and whether the remaining patterns are creating crawl or server work.
HostCupid Web Solutions Private Limited is a Chennai-based company operating since 2018 and providing website development, shared and WordPress hosting, and migration assistance. For a business moving a WordPress or ecommerce site, this distinction is a practical handover check: confirm that live-site visibility settings, robots rules and canonical URLs were not copied from a private staging environment or left inconsistent after migration. The checks remain useful regardless of which hosting provider manages the site.
There is no universal rule to block all parameter URLs or to noindex every page that looks similar. Decide whether the problem is access, visibility, duplication or crawl volume; apply the matching control; then inspect representative URLs and monitor Search Console for the outcome.
Sources
- Robots.txt introduction — Google Search Central · 2025-12-10
- Block Search indexing with noindex — Google Search Central
- Managing crawling of faceted navigation URLs — Google Crawling Infrastructure · 2025-12-18
- Designing a URL structure for ecommerce websites — Google Search Central
- Settings Reading screen — WordPress.org Documentation · 2024-06-08
- Get started with Search Console — Google Search Central · 2025-12-10