Published 30 October 2026
Submitting a sitemap does not guarantee that Google will crawl or index every listed page. A sitemap is a discovery signal: Google still needs to access a URL, receive a working page, and decide whether it belongs in Search results. If important pages are missing, check the URL itself and the site’s technical signals before repeatedly resubmitting the same sitemap.
This guide is for website owners, ecommerce teams and developers using Google Search Console. It focuses on practical checks that apply to WordPress and other content platforms, as well as custom websites.
First distinguish discovery, crawling and indexing
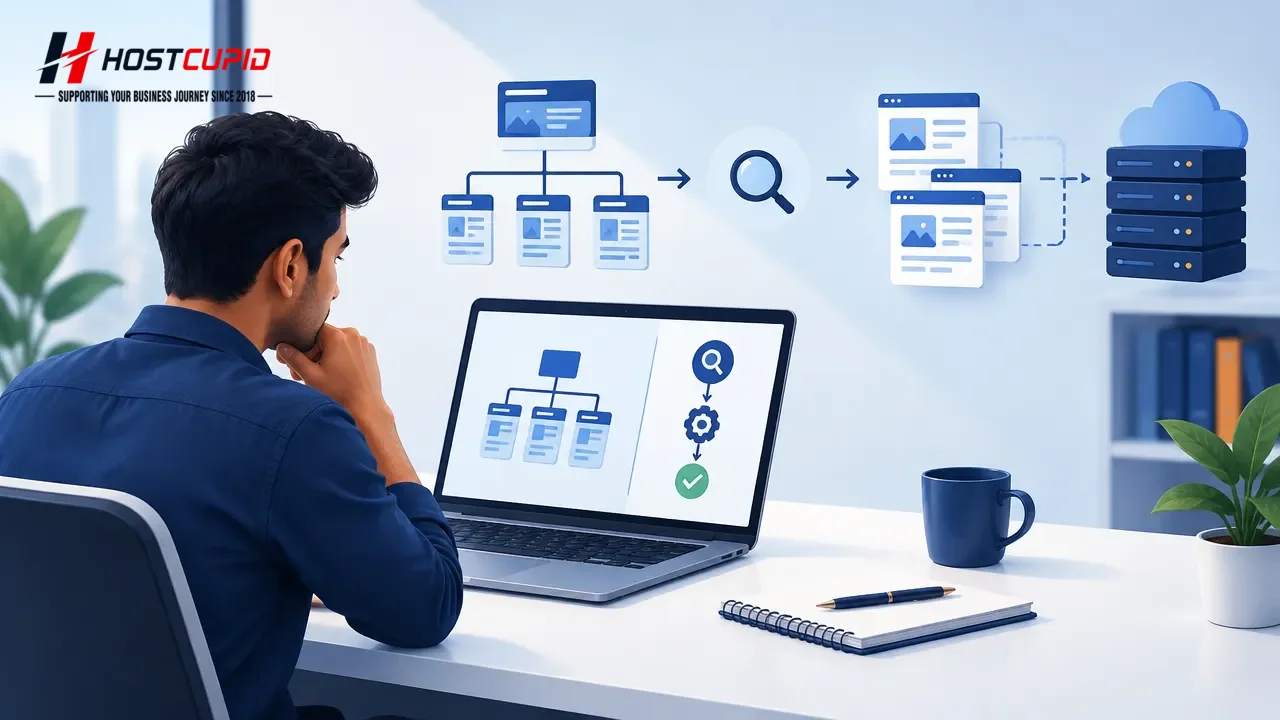
These terms describe different stages. Google can discover a URL from a sitemap or link, crawl it by requesting the page, and then evaluate whether to index it. A URL can therefore be present in a sitemap but not yet crawled, or crawled without being selected for indexing. Meeting technical requirements makes a page eligible; it does not guarantee inclusion.
Start with a small sample of important URLs rather than assuming every listed page has the same issue. Choose a product, service or article page that should be searchable, and inspect it in Search Console’s URL Inspection tool. Compare the reported status with what the page actually serves to a visitor.
Check these six common causes
- The page is blocked from crawling. Review the site’s robots.txt rules and the URL Inspection result. A robots.txt rule controls crawler access; it is not a reliable way to keep a URL out of search results. If Google cannot crawl a page, it may not be able to read page-level instructions such as noindex.
- The URL returns an error or unexpected redirect. Confirm the page loads publicly and returns a successful HTTP 200 response. Check that redirects lead to the intended final page and do not form a chain or loop. A login screen, server error or temporary maintenance page can prevent normal evaluation.
- A noindex instruction is present. Check the page’s HTML for a robots meta tag and inspect HTTP response headers for X-Robots-Tag. If the page should appear in search, remove an unintended noindex through the CMS, plugin or application configuration. Keep noindex on pages intentionally excluded.
- The canonical points elsewhere. A canonical URL tells search engines which version of similar or duplicate pages is preferred. Inspect the declared canonical and compare it with the page you want indexed. A wrong canonical can consolidate signals onto another URL; do not change it unless that destination is genuinely the preferred version.
- The sitemap lists unsuitable URLs. Include the preferred, public URLs you want considered for search, not redirected, error, private, duplicate or deliberately excluded pages. Ensure the sitemap uses complete HTTPS URLs and matches the website’s canonical URL structure.
- The page is thin, duplicated or not useful enough. Technical access alone does not make a page valuable to searchers. Check whether it offers distinct information, accurate details and a clear purpose. For ecommerce sites, avoid creating large numbers of nearly identical filter or parameter URLs without a sound reason.
Use Search Console as a diagnostic workflow
- Inspect the exact URL. Use URL Inspection for a representative page. Review whether Google has crawled it, its indexing status and any detected canonical information. Use the live test where available to check current accessibility; it does not replace the indexed-page report.
- Verify the page in a browser and at HTTP level. Test the public URL without being logged in. Check its final destination, response code, robots directives and canonical tag. If you cannot confidently interpret server headers or application output, ask your developer or hosting administrator to verify them.
- Review the Page Indexing report for patterns. Group affected URLs by template or reason. If only product filters are affected, investigate those rules; if many unrelated pages show server errors, examine site availability and application logs around the reported crawl period.
- Fix the cause, then request a check where appropriate. After correcting an important page, request indexing through URL Inspection or submit an updated sitemap for a larger set of URLs. Repeated requests for the same unchanged page do not force faster crawling, and indexing can take time.
- Monitor instead of repeatedly resubmitting. Keep the sitemap accurate and inspect whether the reported status changes. Avoid changing several unrelated SEO settings at once; that makes it harder to identify which correction mattered.
Important: Do not remove a robots.txt block and add noindex as a quick fix without checking the goal. Google must be able to crawl a URL to see a noindex directive, while robots.txt is designed to control crawling.
When does crawl budget matter?
Most small business websites do not need advanced crawl-budget work. Google’s guidance says that sites without very large or rapidly changing URL inventories can usually focus on maintaining a current sitemap and checking the Page Indexing report. Crawl-budget analysis is more relevant to very large sites, frequently updated catalogues, or websites with many URLs reported as discovered but not indexed.
For an online store, prioritise the URLs that matter to customers: products in stock, useful categories and key service pages. Check whether faceted filters, tracking parameters or internal search create many alternate URLs. Fixing duplicated or low-value URL patterns can make the site easier to manage, but do not block useful pages just to chase an assumed crawl quota.
What this means for hosting and website teams
Some indexing symptoms are application or configuration issues; others may coincide with server availability, slow responses or repeated errors. A hosting change by itself cannot make a page indexable, and an indexing report alone does not prove a hosting fault. Match Search Console evidence with page tests, server logs and recent deployment or plugin changes before deciding what to fix.
HostCupid Web Solutions Private Limited, a Chennai-based company operating since 2018, provides hosting, website development and migration assistance. For a customer moving a site or troubleshooting a newly launched website, a useful support discussion is specific: share the affected URLs, their observed status codes, Search Console messages and the time the issue occurred. That gives the website and hosting teams evidence to investigate without implying that any hosting service guarantees indexing.
Practical takeaway
- Use the sitemap to help Google discover preferred URLs, not as a promise of indexing.
- Check crawl access, HTTP status, noindex and canonical signals on representative pages.
- Use Search Console reports to identify patterns, then verify the site itself.
- Fix the underlying issue and allow time for recrawling; repeated submissions do not guarantee faster results.
A calm, evidence-led diagnosis is safer than changing robots.txt, canonicals or CMS settings in bulk. Start with pages that matter to visitors, confirm what Google can access, and make one targeted correction at a time.
Sources
- Build and Submit a Sitemap
- Google Search Technical Requirements · 2025-12-18
- Block Search Indexing with noindex
- Optimize your crawl budget
- Ask Google to Recrawl Your Website · 2025-12-10