Published 24 October 2026
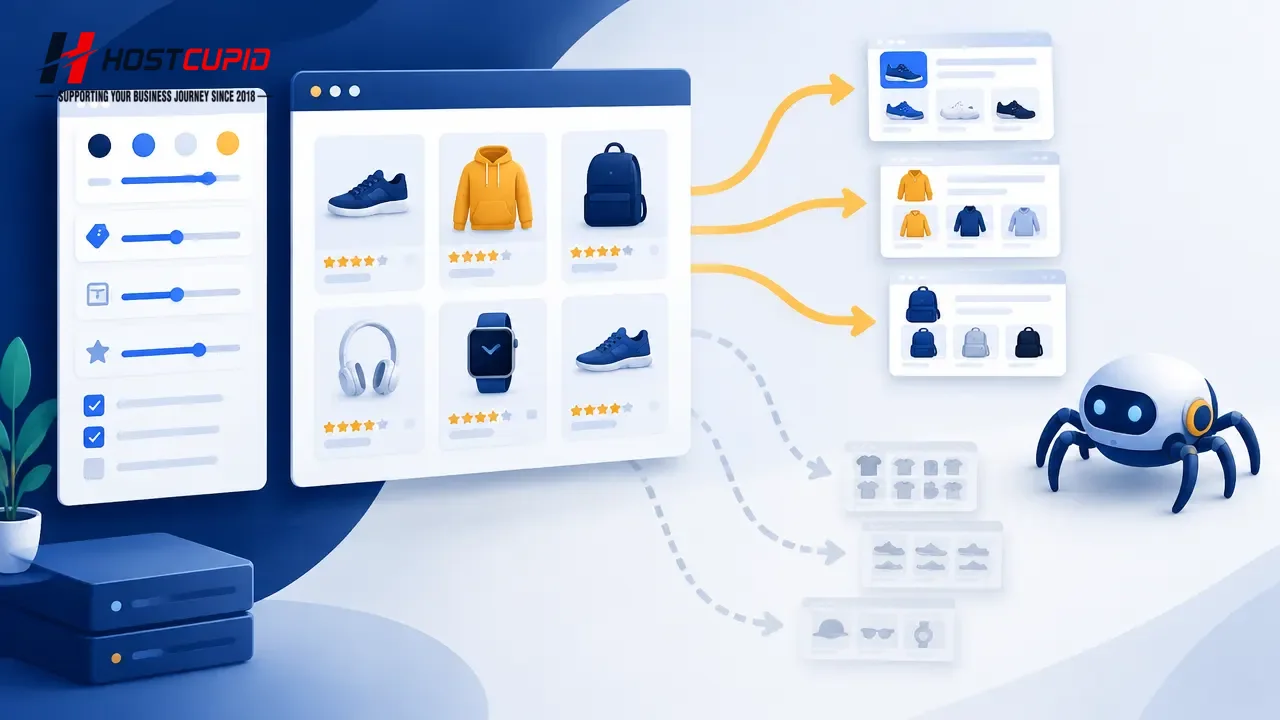
WooCommerce filters can make a large catalogue easier to shop, but each selected colour, size, brand or price range may create another URL. If the combinations multiply, search crawlers can spend time visiting pages that offer little distinct value, while your server handles more requests. The answer is not to block every filter: first decide which filtered pages are useful as landing pages, then control the rest deliberately.
This guide focuses on crawl management for filter URLs, not on choosing which filter pages should rank. It explains how to inspect URL patterns and choose between crawl blocking, canonical signals and index controls. A robots.txt rule controls crawling; it is not a reliable way to remove a URL from Google’s index.
Why can product filters create a crawl problem?
Faceted navigation is a set of controls that lets shoppers refine a listing, such as selecting “cotton”, “blue” and a price range. When each selection changes the URL, combining options can generate many possible addresses, including permutations that show nearly the same products. Google notes that crawling this URL space can use server resources and slow discovery of useful URLs. This matters to ecommerce owners because unnecessary visits can add load without creating a valuable search landing page.
Start by separating two questions: should a URL be crawled, and should it be indexed? These are not identical. If you want a filtered page considered for search, it needs a stable URL, genuinely useful product selection and a crawlable page. If it is simply an alternate display for shoppers, it may not need its own search presence.
Choose the right control for each URL type
- Potentially valuable landing page: Keep it crawlable, make the URL stable and ensure the page offers a distinct, useful selection. Link to it where shoppers can find it.
- Temporary sorting or redundant combinations: Avoid linking these URLs as permanent destinations. If they do not need to appear in search, use an appropriate crawl-control or indexing approach after checking the site’s URL patterns.
- Near-duplicate page that should consolidate: A canonical link can signal the preferred representative URL. It is a hint, not a command, and should point to a page that is genuinely representative of the content.
- Page that must not appear in search: Use an index-control method such as a noindex directive, and make sure the crawler can access the page to read that directive.
Google recommends robots.txt for managing crawl access to unwanted faceted URLs, and describes canonical links and nofollow filter links as other signals. These options solve different problems, so do not paste a broad rule into production simply because a URL contains a question mark.
Audit filter URLs before changing robots.txt
Make a small inventory before editing. Use a browser to apply filters, then note the resulting URL and whether the product list, page title, canonical tag or page content changes. Check combinations in different orders: if “blue then cotton” and “cotton then blue” create separate URLs for the same result, the shop may be exposing avoidable variants.
- List parameter names. Record filter, sort, pagination, tracking and session parameters separately. Do not assume every query parameter is disposable.
- Check real usage. Review analytics, Search Console and internal links for filtered URLs that attract shoppers, external links or meaningful search impressions.
- Identify pages worth keeping. A curated category such as “blue cotton shirts” may help shoppers and deserve a stable, useful page. A temporary “price low to high” view usually serves a different purpose.
- Inspect canonical output. View the rendered page source or use browser developer tools to confirm the canonical points where intended. Check that sitemap entries and internal links consistently use preferred URLs.
- Test the proposed pattern. Match only known filter parameters. Check a product page, category page, pagination URL, cart and checkout path before publishing a robots.txt change.
Robots.txt, canonical and noindex are not interchangeable
A robots.txt disallow rule asks crawlers not to fetch matching URLs. It does not guarantee the URL disappears from search: Google may still know the address from links, while being unable to see the page’s content or noindex tag. If the objective is to exclude a page from search, Google says the page must remain crawlable so the noindex directive can be read.
A canonical link indicates which URL should represent duplicate or very similar pages. It does not prevent crawling, and Google can choose a different canonical based on the signals it sees. A permanent redirect is more appropriate when duplicate URLs should genuinely resolve to one destination. Avoid pointing every filtered page to a broad category if the filtered content is substantially different or useful in its own right.
Important: Do not combine a robots.txt block with a noindex tag on the blocked URL and expect Google to read the tag. If uncertain, test the intended behaviour on a small URL group and inspect what Googlebot can access before expanding the rule.
Verify the change and protect the shopping journey
After deploying a change, check the live robots.txt file and test representative URLs, including a filter combination you intend to block and one you intend to keep accessible. Use Search Console’s URL Inspection for priority pages to review crawl access, indexing status and the Google-selected canonical. Recheck category and product discovery, plus normal shopper functions such as filtering, pagination and links back to product pages. Avoid changing several unrelated URL rules at once; that makes errors harder to trace.
For a small shop, a cautious manual audit may be enough. For a large catalogue, ask the developer or ecommerce agency to document the parameter rules and test them on staging. A migration or website-development project is also a good moment to review filter URL behaviour before launch. HostCupid provides website development and migration assistance; a store owner considering either service can use the URL inventory above to explain which filtered pages must remain accessible and which should be consolidated or kept out of search.
The practical goal is not to minimise every crawl or to index every filter combination. Keep useful product and category pages discoverable, reduce avoidable URL duplication, and verify crawler directives alongside the customer experience. That balance helps shoppers use filters while keeping technical changes grounded in the actual structure of the shop.
Sources
- Managing crawling of faceted navigation URLs
- Block Search indexing with noindex
- How to specify a canonical URL with rel="canonical" and other methods · 2026-07-10
- Fix canonicalization issues · 2026-08-21